Multiagent RAG Platform
The document pipeline behind an enterprise AI knowledge platform — PDF to grounded, retrieval-augmented answers.
Overview
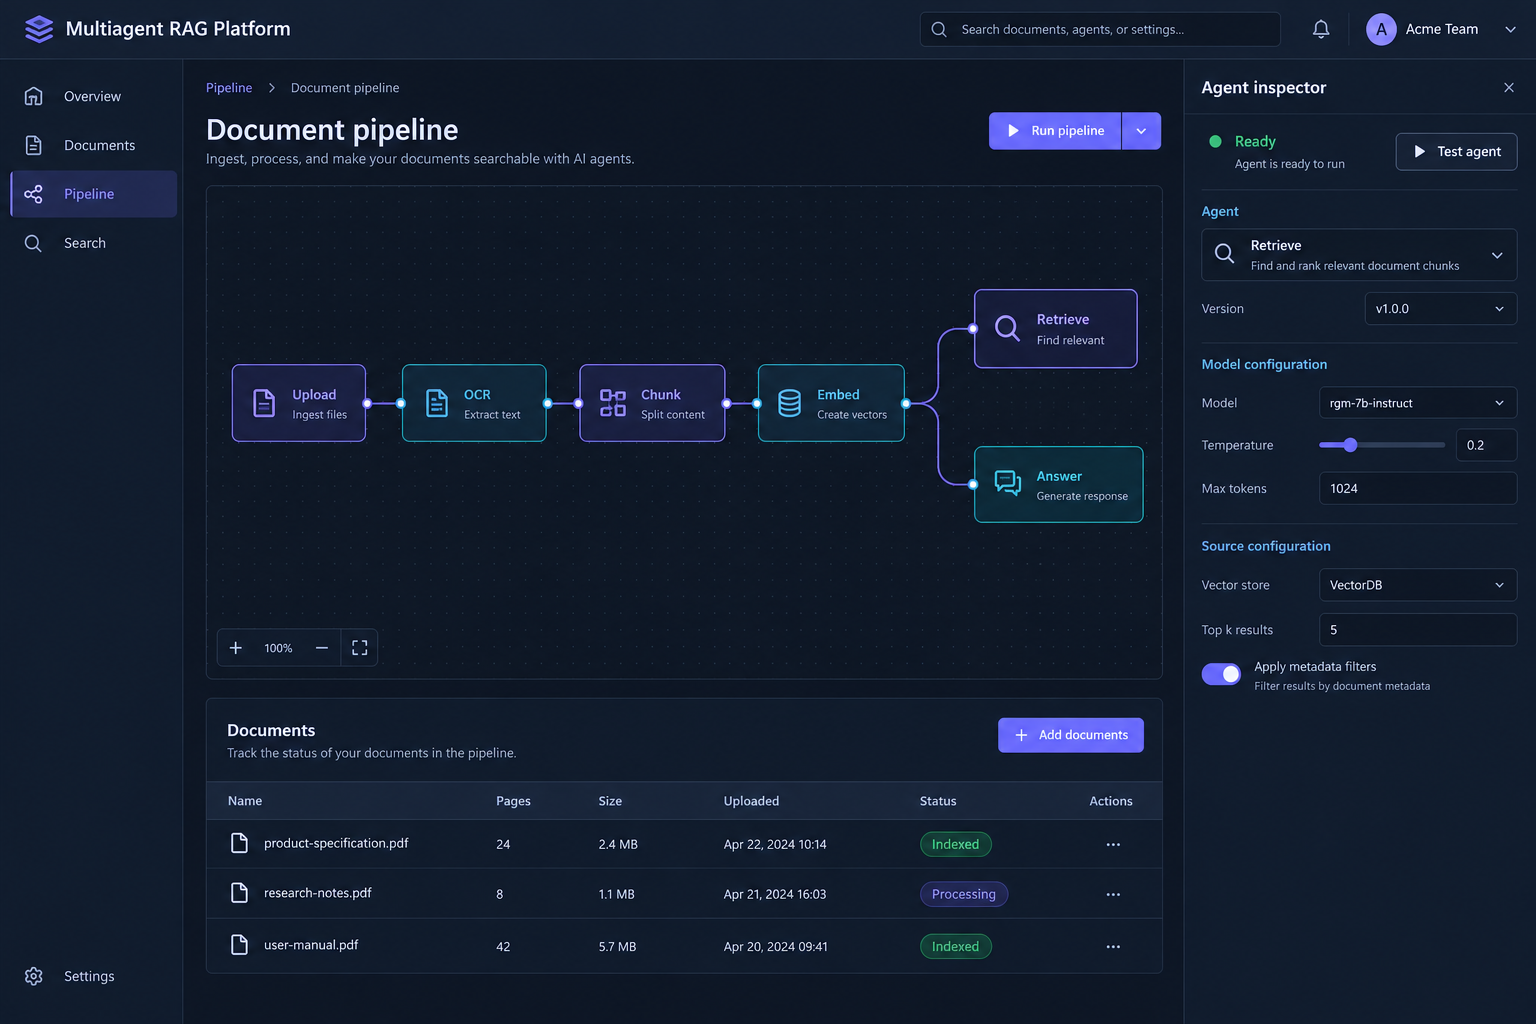
An asynchronous ingestion pipeline for a teacher-facing knowledge platform. Teachers upload large PDFs; a background worker OCRs, chunks, and embeds them into Pinecone so students can query notes with grounded answers.
Contribution Fabapps Lab
Problem
A 200-page PDF can't be processed inside an HTTP request — it would take minutes and time out. Uploads and processing had to be decoupled without losing jobs on crash or restart.
Approach
- 01
Direct-to-S3 multipart upload: the frontend splits into 5MB parts, requests presigned URLs, and the server assembles on completion.
- 02
Queue the heavy work via BullMQ on Redis — the API responds in under a second while a separate worker processes at concurrency 8.
- 03
Worker OCRs the PDF (digital and scanned), then recursive chunking (1000/200 overlap) at natural boundaries.
- 04
Memory-safe mini-batches: embed with OpenAI and upsert to Pinecone in small groups with retry, clearing memory between batches.
Outcome
- Sub-second upload response; multi-minute processing moved fully to the background.
- Jobs survive crashes and restarts — Redis guarantees no two workers grab the same job.
- Stable memory on 200+ page documents via batched embedding and cleanup.
- Grounded RAG answers over uploaded notes with OpenAI embeddings in Pinecone.